In this guide you will learn how to weigh the tradeoffs of AI training access. We will keep it practical, with clear steps, visual breakdowns, and specific actions you can take today. The first step in any AI visibility project is to run a robots.txt AI crawler test on your website so you know exactly where you stand against the 265 bots we track across 8 categories.
Key Takeaways
- The Pros and Cons of Allowing AI Training Crawlers is a practical, repeatable process, not a one-time fix.
- Most AI visibility problems trace back to access, not content.
- You can verify every change with the AI crawler tester and the robots.txt validator.
- Document your approach so the whole team applies it consistently.
Turning a Policy Decision Into a Live Configuration
Write the policy in plain language first
Agree in ordinary sentences what a site weighing AI training access wants each kind of bot to do before anyone touches a directive.
Map each intention to a specific user agent
Turn every sentence of the policy for a site weighing AI training access into a named token, using your licensing terms and the share of traffic each bot sends as the reference list.
Record the current state before changing it
Run an AI crawl checker and save the result. Without a baseline you cannot demonstrate the change worked, and you cannot roll back with confidence.
Generate the file rather than editing it
Use a robots.txt file generator to write a training access decision into correct syntax with explicit groups. Hand-edited files collect rules that each look plausible and together contradict each other.
Validate, publish, then set an owner and a date
Check it with a robot checker, publish, and assign a named owner with a review interval. An unowned policy is indistinguishable from no policy within a year.
The Question Behind the Training Access Tradeoff
The debate is unusually hard to settle because both sides of the ledger are difficult to measure. The claimed benefit, being represented inside a model so it recommends you, produces no log entry and no referrer. The claimed cost, having your work absorbed into a system that answers questions without sending anyone to you, also produces no log entry. Two invisible quantities are being weighed, which is why the argument tends to be won by whoever is more confident rather than whoever is more right.
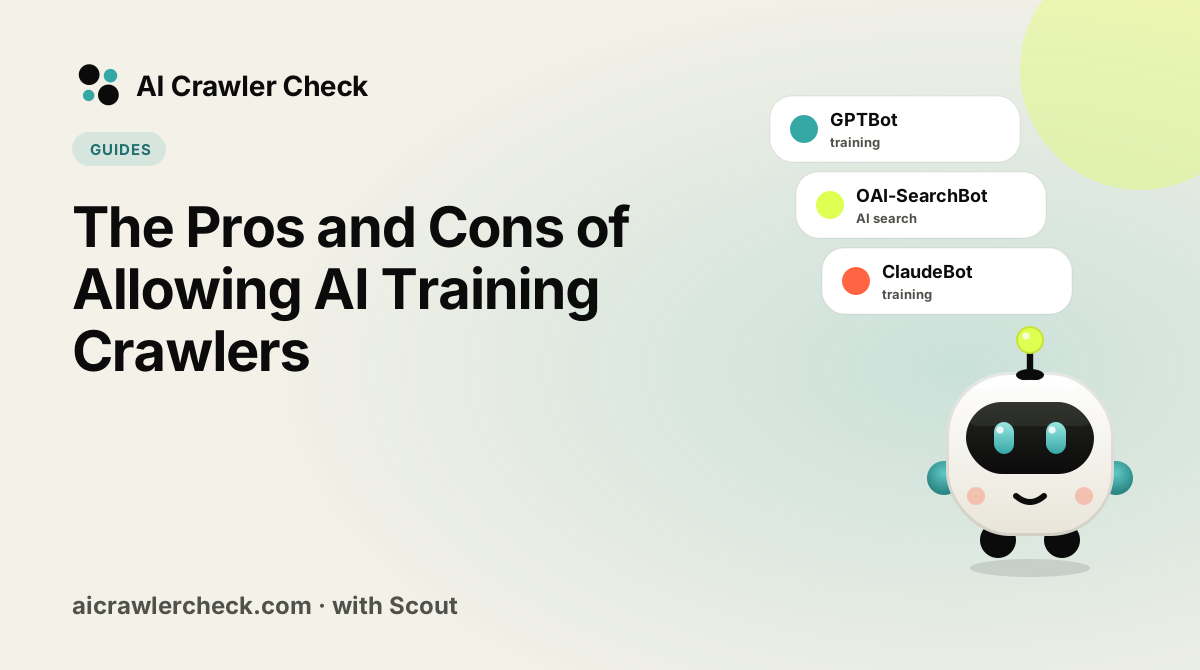
What can be measured is the difference between crawler types. Training crawlers gather text for future model updates and give nothing back in the moment. Retrieval crawlers fetch a page to answer a question being asked right now, and those visits can produce a citation and a click. Collapsing both into a single position on AI access means arguing about the invisible case while accidentally deciding the measurable one.
The Training Access Decisions That Actually Matter
The benefit of training access is real but slow and unattributable
If a model has read your material it can describe your product without a live fetch, which matters for the large share of questions answered without any browsing at all. That is a genuine benefit. It arrives on the model release cycle rather than the publishing cycle, it cannot be attributed to any particular page, and it degrades as the model ages. Anyone promising to measure it directly is selling a proxy.
The cost is concentrated in a narrow class of content
For most pages, training ingestion costs close to nothing, because the page was never going to earn a visit for the fact it contains. The cost concentrates where the content IS the product: original datasets, priced research, reference tables people would otherwise pay for. A single site can hold both classes, which is why a blanket answer overpays on one side or the other.
Blocking training does not protect you from being described
A model can characterise your business from what others have written about you, from your own marketing copy quoted elsewhere, and from retrieval fetchers you left open. Blocking training crawlers removes your ability to shape that description while leaving the description itself intact. In several cases the practical result of a training block is a summary built entirely from competitor comparisons and old press coverage.
The asymmetry favours starting open on documentation
Allowing access to explanatory content is nearly costless and occasionally very valuable, while blocking it is nearly always a small loss. The reverse holds for proprietary data. So the defensible starting position is open where the content is explanation and closed where the content is the asset, rather than a single stance argued from first principles about the whole site.
What Goes Wrong Most Often With the Training Access Tradeoff
Treating retrieval crawlers as part of the training question
The costliest version of this debate ends with a decision to block AI training that is implemented as a block on every AI user agent. Training access, whose value was uncertain, is now closed. Retrieval access, whose value was the measurable part, is closed too. The site stops appearing as a cited source in live answers, which shows up as a slow decline nobody connects to the policy change, because the change was recorded as being about training data.
The Training Access Test Worth Running Now
The check that matters here: List your three most valuable pages and ask, for each, whether you would rather it were quoted with attribution or never quoted at all. If the answer differs between them, a single sitewide stance is already wrong.
Where to Go From Here
Training Access is one piece of a larger picture. The AI crawler directory documents every crawler we track with its operator, purpose and safety rating, and the bulk AI crawler check audits many sites in one pass if you manage a portfolio.
Your Training Access Action Checklist
Applied to The Pros and Cons of Allowing AI Training Crawlers, it looks like this:
- □Establish a baseline with an AI crawler test and write down the score before you change anything.
- □Write the policy in plain language first.
- □Validate the change with the robot checker before it reaches production.
- □Map each intention to a specific user agent.
- □Record the current state before changing it.