In this guide you will learn how to choose between WAF blocking and robots.txt for AI. We will keep it practical, with clear steps, visual breakdowns, and specific actions you can take today. The first step in any AI visibility project is to run a free AI crawler check on your website so you know exactly where you stand against the 265 bots we track across 8 categories.
Key Takeaways
- Cloudflare AI Bot Blocking vs robots.txt: Pros and Cons is a practical, repeatable process, not a one-time fix.
- Most AI visibility problems trace back to access, not content.
- You can verify every change with the GPTBot and ClaudeBot access check and the robots txt validator.
- Document your approach so the whole team applies it consistently.
Blocking Bad Traffic Without Blocking Citations
Inventory what is currently being blocked and by what
List every layer that can refuse a request on a Cloudflare site weighing bot blocking against robots.txt and record what each one blocks on the Cloudflare bot settings and your robots.txt side by side today.
Verify the identity of the agents you care about
Check that requests to the Cloudflare bot settings and your robots.txt side by side claiming to be a known AI crawler come from the ranges that operator publishes.
Distinguish abusive volume from unwanted purpose
Separate bots that hit the Cloudflare bot settings and your robots.txt side by side too hard from bots you simply do not want, because rate limits solve one and blocks solve the other.
Test the external result rather than the config
Judge the setup for a Cloudflare site weighing bot blocking against robots.txt by what an outside request to the Cloudflare bot settings and your robots.txt side by side receives, not by what the dashboard says.
Recheck after every infrastructure change
Bot-management defaults change, CDN features get enabled, and vendors add protections without asking. Validate the file with a robots.txt validator and re-scan on a schedule.
What Edge Controls Against File Directives Do, and What They Do Not
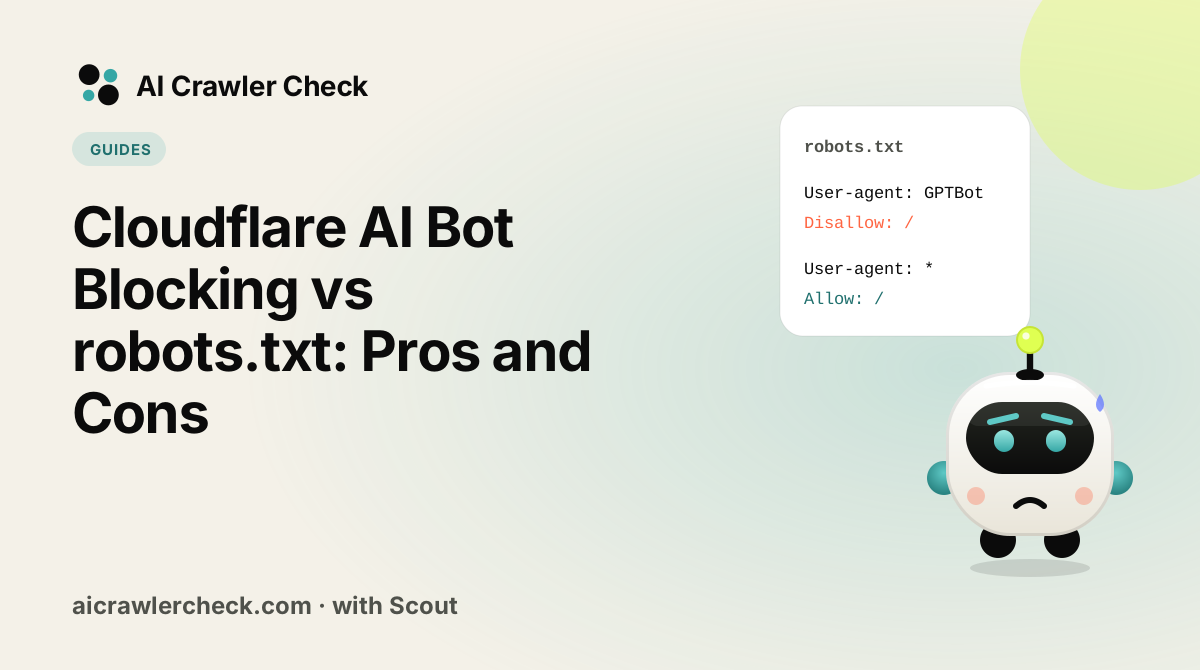
These two are constantly compared as competing products when they are not the same kind of thing. A file directive is a published request that cooperative agents choose to honour. An edge control is enforcement that applies whether the agent cooperates or not. One states intent and the other imposes it, so asking which is better is the wrong question. The right question is which of your requirements need enforcing and which only need declaring.
The reason this cannot be settled by preference is that the bot population is split. A majority of catalogued agents are recorded as honouring robots.txt, which makes the file genuinely effective for them and far cheaper to maintain than any rule set. But a substantial minority do not honour it, and others are recorded as inconsistent or simply unknown. Any requirement that actually matters has to survive that minority, and no file directive can make it. Meanwhile enforcing everything at the edge throws away the one thing the file does that enforcement cannot: it tells well behaved agents what you want in a form they can read before they fetch.
Where People Get Edge Controls Against File Directives Wrong
Use the file to declare intent and the edge to enforce consequences
The division that holds up is by what happens if the agent ignores you. If the answer is that you would accept it, the file is the right home, because it costs nothing and needs no infrastructure. If the answer is that you would not accept it, the file is insufficient on its own regardless of how carefully it is written. Most sites need both, expressing the same policy in two registers, and the mistake is treating the choice as either or.
Keep the two statements consistent, because divergence is the usual bug
When both layers exist they drift. Someone adds an edge rule during an incident and nobody updates the file, so the published policy now says one thing and the enforced policy does another. Cooperative agents read the file, comply with what it says, and are blocked anyway, which is the worst combination available: you lose the citation and you also look as though you invited the fetch. Review both together, and treat a discrepancy as a defect rather than as redundancy.
Related: how AI engines choose their sources
Understand that an edge rule can fail closed in ways a file cannot
A file directive has a small blast radius. If it is wrong, agents that read it behave differently, and correcting the file corrects the behaviour on their next fetch. An edge rule sits in the request path, so a rule that is broader than intended can remove access for agents nobody meant to touch, immediately and without any signal. That is an argument for testing edge changes from outside and for making them narrow, not an argument against using them.
Choose based on your own operational reality, not on which is stricter
Both layers need an owner and a review habit, and they place the burden differently. A file directive lives in the repository, is reviewed like code, and is easy to reason about. An edge control lives in a dashboard, often outside version control, and is frequently changed by whoever is handling an incident. If nobody owns the dashboard, an edge only policy will decay faster than a file only one, whatever its theoretical advantages. The stricter mechanism is not the better one if it is the one you cannot maintain.
The Control Placement Failure That Hides in Plain Sight
Assuming an edge rule makes the file redundant
The reasoning sounds airtight: enforcement covers everything a request could cover, so why maintain a file as well. What it misses is that the file is the only channel that communicates before the fetch happens. Remove it and cooperative agents lose the ability to respect a boundary they would have respected, so they now discover your policy by being refused. You get the same restriction with worse signalling, and you lose the record of what your policy actually is, which is the thing anyone reviewing the decision later needs to read.
How to Confirm Edge Controls Against File Directives Behave the Way You Think
The check that matters here: Write out your intended policy in one column, then what robots.txt says and what the edge enforces in two more. Every row where the three disagree is either a bug or an undocumented decision.
Where to Go From Here
Control Placement is one piece of a larger picture. The AI bot directory documents every crawler we track with its operator, purpose and safety rating, and the batch checker audits many sites in one pass if you manage a portfolio.
Your Control Placement Action Checklist
Applied to Cloudflare AI Bot Blocking vs robots.txt, it looks like this:
- □Establish a baseline with an AI crawler checker and write down the score before you change anything.
- □Inventory what is currently being blocked and by what.
- □Validate the change with the robots checker before it reaches production.
- □Verify the identity of the agents you care about.
- □Distinguish abusive volume from unwanted purpose.